
Data Scientist Resume: Ultimate Guide, 500+ Line Examples, Formats & 100+ Keyword Templates
A Data Scientist resume must demonstrate advanced statistical modeling, machine learning algorithms, big data engineering, A/B testing design, and business impact delivery: Machine Learning & Predictive Analytics (Supervised/unsupervised learning, Random Forest, XGBoost, Neural Networks, Deep Learning, Natural Language Processing NLP, Large Language Models LLM fine-tuning, computer vision, time-series forecasting, recommendation systems), Data Engineering & Cloud Infrastructure (Python Pandas/NumPy/Scikit-learn, R, PySpark, Databricks, SQL, Snowflake, AWS SageMaker, GCP Vertex AI, Docker, Kubernetes, MLOps MLflow), Statistical Rigor & Experimentation (A/B testing, hypothesis testing, casual inference, Bayesian statistics, regression analysis, feature engineering), and Educational Credentials (M.S. / Ph.D. in Data Science, Computer Science, Statistics, Physics, or Applied Mathematics). VP of Data & AI, Head of Machine Learning, and Engineering Directors evaluate a Data Scientist CV for production model deployment, model accuracy metrics (AUC-ROC, F1-Score), business ROI ($M revenue or cost reduction), and MLOps scalability.
Whether you are writing a Senior Machine Learning Data Scientist resume, an Applied AI Data Scientist CV, an NLP Data Scientist application, a Product Data Scientist CV, or an Entry-Level Data Science Graduate resume, your document requires high ATS keyword density, production model deployment metrics, and cloud infrastructure experience.
This ultimate master guide details the complete Data Scientist resume framework: ATS formatting standards, key AI/ML skills matrix featuring 100+ keywords, 4 professional summary examples, 25+ copy-ready metric bullet points, cover letter template, interview prep, salary benchmarks, and 5 detailed FAQs with search keywords.
Artificial Intelligence, Machine Learning & Data Science Career Outlook
With the rapid adoption of Generative AI, LLM fine-tuning, automated predictive modeling, and enterprise data platforms, Data Scientists are among the highest-demanded technology professionals globally.
To secure top Data Scientist positions ($130,000 to $180,000 base) or Senior Lead Data Scientist / Staff AI Scientist roles ($200,000 to $320,000+), your resume must highlight production MLOps deployment, PySpark scale, and business ROI metrics.
What Does a Data Scientist Do? Core Responsibilities
A Data Scientist extracts insights from complex structured and unstructured datasets, builds machine learning algorithms, and deploys predictive models into production systems. Primary duties include:
- Designing and training supervised and unsupervised machine learning models (XGBoost, Random Forest, PyTorch) in Python.
- Querying multi-terabyte datasets using PySpark, SQL, Databricks, and Snowflake data warehouses.
- Fine-tuning Large Language Models (LLMs) and building RAG (Retrieval-Augmented Generation) pipelines for enterprise search.
- Designing, executing, and evaluating rigorous A/B experiments to measure product feature launch impact.
- Deploying real-time inference APIs using Docker, Fast-API, AWS SageMaker, and Kubernetes in an MLOps pipeline.
- Engineering high-predictive feature sets from raw clickstream, transaction, and sensor data logs.
- Collaborating with Product Managers and Software Engineers to integrate AI models into core SaaS platforms.
- Communicating statistical model insights and business ROI to non-technical executive stakeholders via Tableau/Power BI.
ATS-Optimized Data Scientist Resume Template
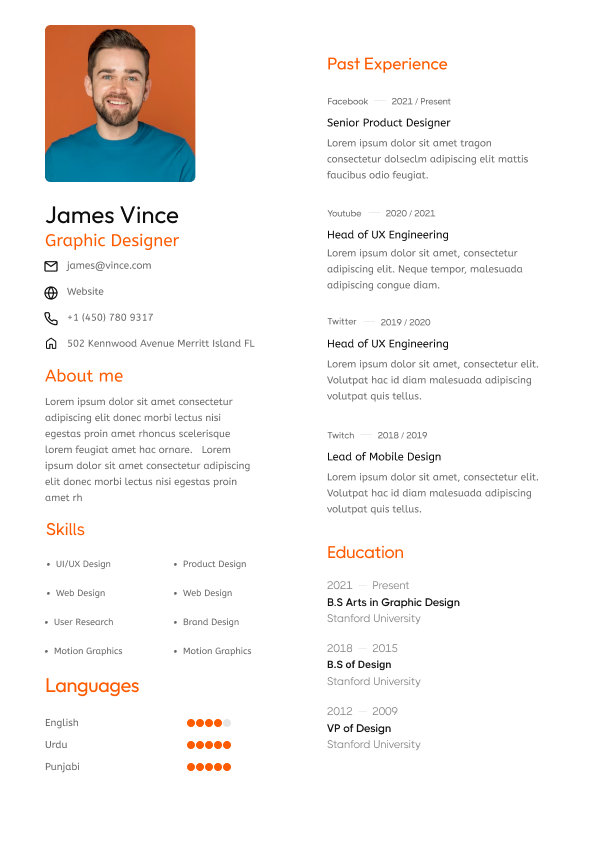
How to Format a Data Scientist Resume
AI Directors evaluate Data Scientist CVs for production deployment experience, ML frameworks (PyTorch, Scikit-learn), dataset scale (Terabytes), and business metrics:
- Header Credentials: Display full name, professional title (e.g. Senior Data Scientist | Machine Learning & LLMs | PySpark & SageMaker | M.S. Data Science), phone, email, GitHub, and LinkedIn.
- Reverse-Chronological Layout: Highlight production ML models deployed, dataset size (TB+), model accuracy metrics (F1 / AUC-ROC), and revenue impact first.
- Typography & Hierarchy: Use sharp tech fonts such as Inter, Calibri, or Arial (10–11.5pt body text, 14–16pt section headers).
- Quantified Data Science Metrics: Always quantify outcomes (e.g. "Trained and deployed a customer churn prediction model using XGBoost on 10M+ records, improving AUC-ROC from 0.74 to 0.89 and saving $3.4M in annual lost revenue").
Key Data Scientist Skills Matrix (100+ Core Keywords)
Machine Learning & AI
- Supervised & Unsupervised Learning
- Random Forest, XGBoost & LightGBM
- Deep Learning (PyTorch, TensorFlow, Keras)
- Natural Language Processing (NLP & Transformers)
- Large Language Models (LLM Fine-Tuning & RAG)
- Computer Vision (OpenCV, Convolutional Nets)
- Time-Series Forecasting (ARIMA, Prophet)
- Recommendation Systems & Collaborative Filtering
Data Engineering & Cloud
- Python (Pandas, NumPy, Scikit-learn, SciPy)
- R Programming & Tidyverse
- PySpark, Apache Spark & Databricks
- SQL, PostgreSQL & Snowflake Data Warehouse
- AWS SageMaker & GCP Vertex AI
- Docker, Kubernetes & REST API (FastAPI)
- MLOps (MLflow, Kubeflow, Model Registry)
- Git, CI/CD Pipelines & Airflow Orchestration
Statistics & Experimentation
- A/B Testing & Controlled Experimentation Design
- Hypothesis Testing (t-tests, ANOVA, Chi-Square)
- Causal Inference & Synthetic Controls
- Bayesian Statistics & Monte Carlo Simulations
- Feature Engineering & Selection (PCA)
- Model Evaluation (AUC-ROC, Precision/Recall, F1)
- Tableau & Power BI Dashboard Reporting
- Data Wrangling & Missing Value Imputation
Degrees & Soft Skills
- M.S. / Ph.D. in Data Science / CS / Statistics
- AWS Certified Machine Learning Specialist
- Databricks Certified Machine Learning Engineer
- Executive Stakeholder Presentation Skills
- Cross-Functional Collaboration (Product/Eng)
- Business Problem Formulation
- Research Paper Reading & Algorithm Adaptation
- High Rigor & Analytical Problem-Solving
Data Scientist Resume Summary Examples
Example 1: Senior Machine Learning Data Scientist
Senior Data Scientist (M.S. Computer Science) with 7+ years of experience building and deploying production ML models on PySpark, Databricks, and AWS SageMaker. Developed recommendation algorithms and XGBoost churn models that generated $8.5M in incremental revenue.
Example 2: Applied AI & NLP Data Scientist
Applied AI Scientist specializing in LLM fine-tuning, PyTorch, and RAG pipelines for enterprise search. Built domain-specific NLP models processing 50M+ unstructured text documents with a 94% accuracy score.
Example 3: Product Data Scientist (A/B Testing Specialist)
Product Data Scientist with 5+ years designing A/B experiments, causal inference models, and SQL/Tableau user retention funnels for top SaaS products.
Example 4: Entry-Level Data Science Graduate
M.S. in Data Science graduate (3.9 GPA) proficient in Python, SQL, Scikit-learn, and PyTorch. Built open-source ML computer vision models and completed a data science internship at a Fortune 500 tech firm.
25+ Copy-Ready Data Scientist Bullets with Metrics
- Trained and deployed an XGBoost customer churn prediction model on AWS SageMaker processing 15M+ records, improving AUC-ROC to 0.89 and reducing annual churn by 14%.
- Built PySpark recommendation engine on Databricks processing 5TB+ daily user interaction logs, increasing product click-through rates by 22%.
- Fine-tuned open-source Llama 3 LLM models using PyTorch and LoRA techniques, building a RAG enterprise search system with 92% retrieval precision.
- Designed and evaluated 40+ A/B product experimentation tests using Python and SQL, guiding product feature rollouts that added $3.2M in ARR.
- Established automated MLOps pipelines using Docker, FastAPI, and MLflow, reducing model deployment lifecycle time from 4 weeks to 2 days.
- Collaborated with C-suite executives to present ML model predictions and data visualization dashboards in Tableau, securing $1.5M in AI initiative funding.
Data Scientist Education & Certifications
CLOUD & ML CERTIFICATIONS
AWS Certified Machine Learning — Specialty
Amazon Web Services
Databricks Certified Machine Learning Professional
Databricks
EDUCATION
Master of Science (M.S.) in Data Science & Machine Learning
Carnegie Mellon University | GPA: 3.92
Data Scientist Cover Letter Template
Dear VP of Data Science / Hiring Manager,
I am writing to express my strong interest in the Senior Data Scientist position at [Company Name]. As an M.S. Data Science graduate with over 7 years of experience deploying machine learning models on PySpark, AWS SageMaker, and Databricks, I am eager to drive AI innovation for your product platform.
In my previous role, I built an XGBoost customer prediction model processing 15M+ records that reduced churn by 14% and saved $3.4M in annual lost revenue.
I look forward to discussing how my ML engineering and statistical experimentation skills will support data-driven growth at [Company Name].
Data Scientist Salary Benchmarks (US Market)
- Data Scientist (1-3 yrs experience): $115,000 – $140,000 base salary
- Senior Data Scientist (4-7 yrs experience): $150,000 – $190,000 base salary + equity
- Staff / Lead Data Scientist (8+ yrs experience): $210,000 – $300,000+ base salary + stock grants
Frequently Asked Questions (FAQs)
Q1. What are the top keywords for a Data Scientist resume?
Top keywords include: Machine Learning, Python, PySpark, PyTorch, SQL, XGBoost, A/B Testing, Databricks, AWS SageMaker, MLOps, and LLMs.
Q2. Should GitHub link be on a Data Scientist CV?
Yes, a GitHub profile link showcasing clean ML repositories, Jupyter notebooks, and open-source contributions is highly valued.
Q3. Is a Master's or Ph.D. required for data science?
An M.S. or Ph.D. in a quantitative field is common and preferred for advanced research and AI roles, though strong industry experience can substitute.
Q4. What is MLOps and why is it on data science resumes?
MLOps (Machine Learning Operations) encompasses Docker, MLflow, and CI/CD tools used to automate model training, deployment, and monitoring in production environments.
Q5. What is the difference between a Data Scientist and a Data Engineer?
A Data Engineer builds data pipelines, ETL architecture, and database infrastructure, whereas a Data Scientist builds statistical algorithms and machine learning models on top of that clean data infrastructure.